google-surf-mcp
MCP search server with automatic knowledge graph construction · Top 1% on MCP TOPLIST
Built with TypeScript · MCP · SurrealDB / RocksDB · Tree-sitter · Multilingual E5 · Graphology · Playwright
WHY
Agents often repeat the same searches because useful papers, code, and sources disappear with the conversation. I built a search server using Model Context Protocol (MCP) that automatically captures search and extraction results in a project-scoped local knowledge graph.
The next search combines that accumulated knowledge with fresh web results. Retrieval-augmented generation (RAG) can then reuse the underlying documents and code while preserving their sources. Projects stay separate, with verified links allowing knowledge reuse across selected projects.
Public open-source MCP server
Search, extraction, project memory, and health
Automatic capture with ontology and source lineage
HOW
Search once, accumulate knowledge, and retrieve it with fresh evidence
A local broker owns the SurrealDB / RocksDB connection, allowing multiple MCP sessions to share storage without competing database writers.
- 01 Search and extract
Search web pages and papers, extract HTML / PDF bodies, and index code files, symbols, imports, and calls with Tree-sitter.
- 02 Capture and link
Store results automatically. An ontology defines entity and relation types; source lineage connects documents, chunks, evidence, and claims. Plans and decisions are recorded when supplied by the host.
- 03 Retrieve and rank
Run exact, BM25 keyword, vector, and graph searches. Personalized PageRank (PPR) expands related evidence; Reciprocal Rank Fusion (RRF) combines ranks before one shared reranker.
- 04 Reuse and inspect
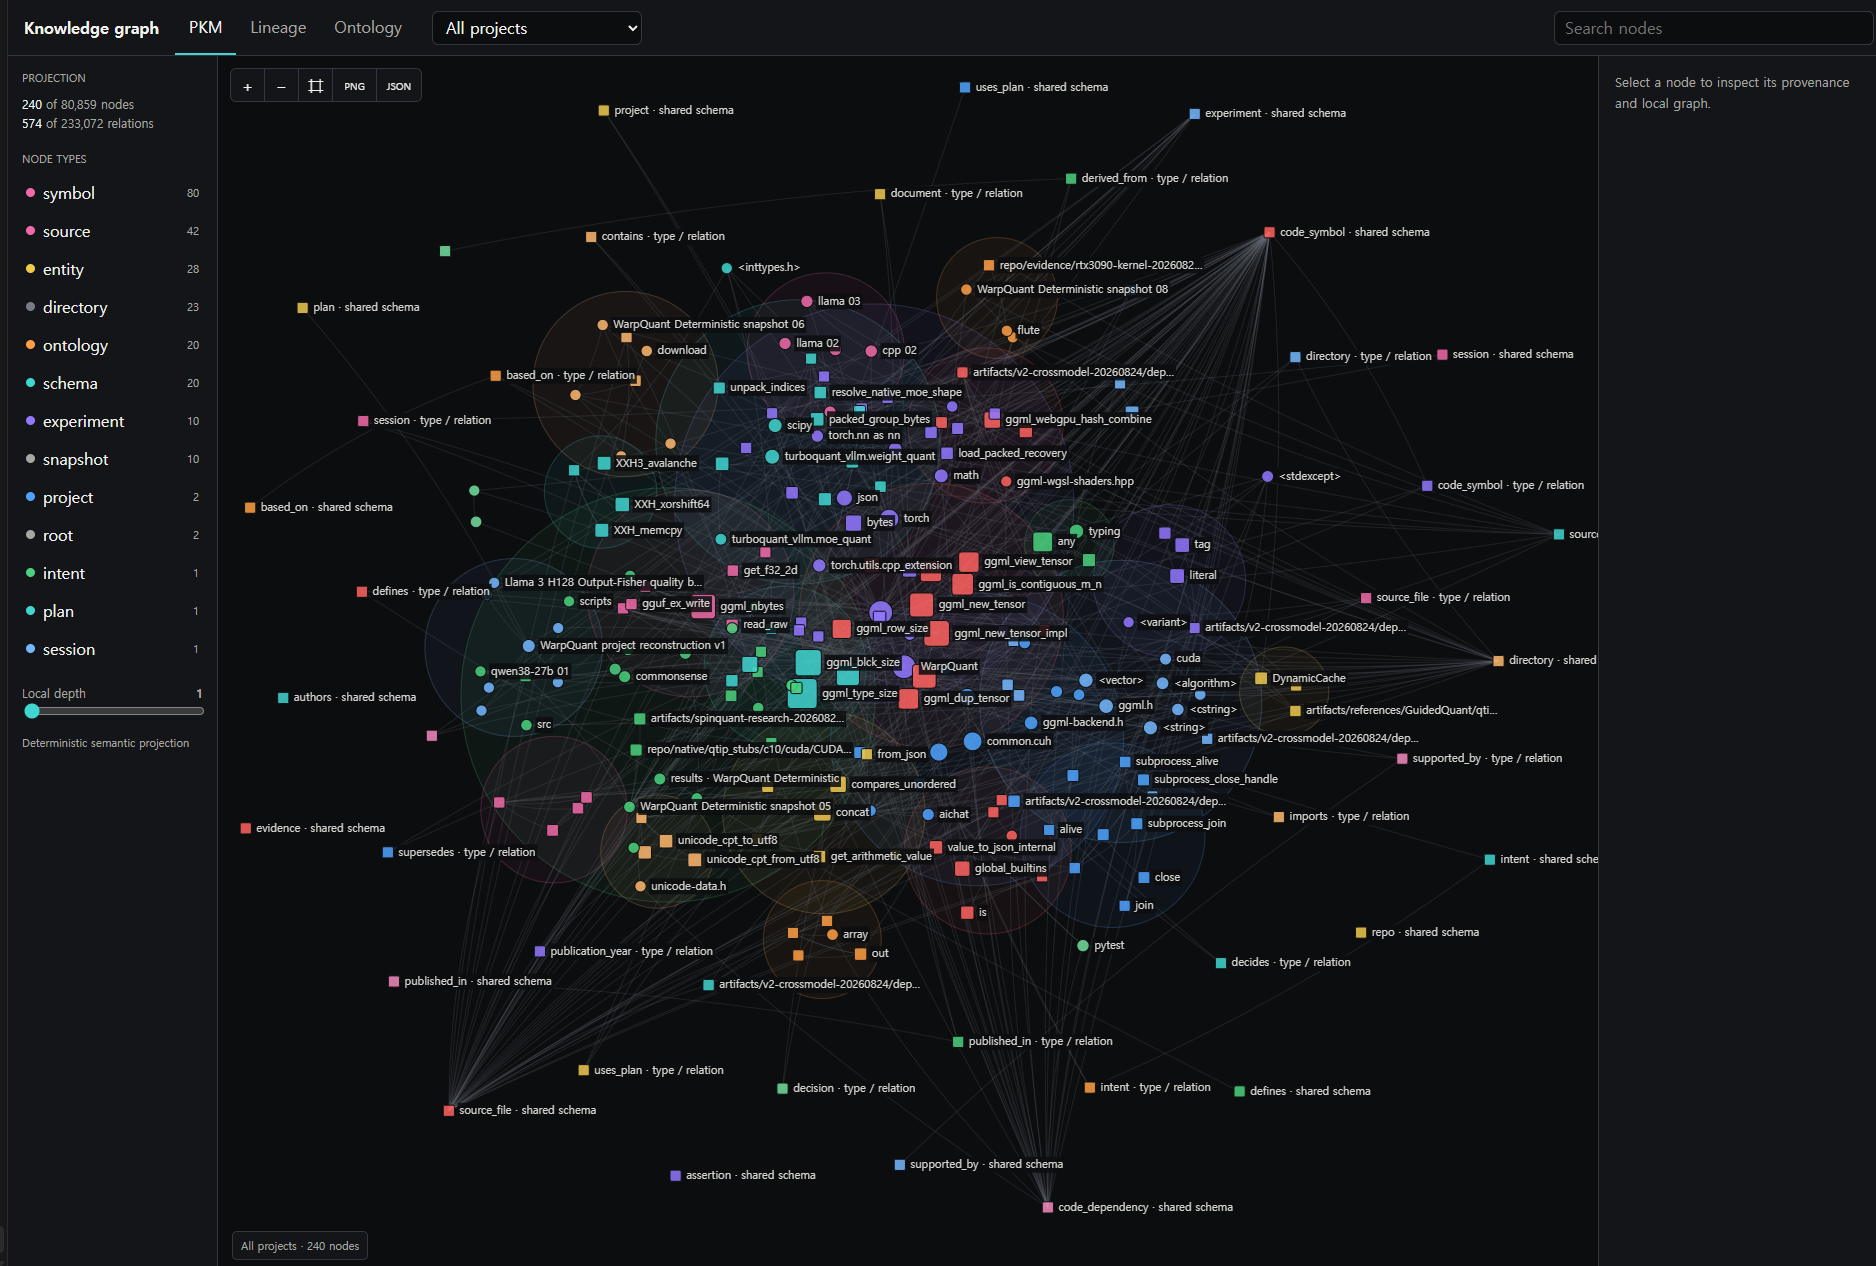
Connect projects through matching DOIs, repository URLs, or explicit aliases. Inspect knowledge, ontology, and lineage in an interactive graph or export to Neo4j import files.
RESULT
Contribution
- Designed and implemented the search-to-knowledge pipeline, shared storage broker, code index, versioned ontology, source lineage, hybrid retrieval, and graph viewer.
- Maintained browser / API routing, parallel search, CAPTCHA recovery, and protections against requests to private network addresses while publishing the npm package.